
5.1 KiB
OptMem
Permanent memory for AI agents. Nothing is ever deleted, and what the agent reads at wake is always the same size.
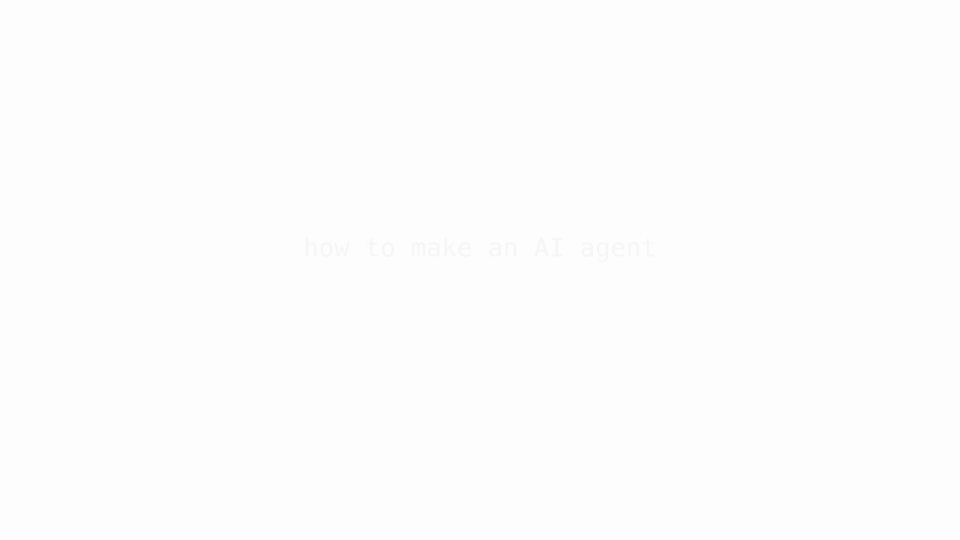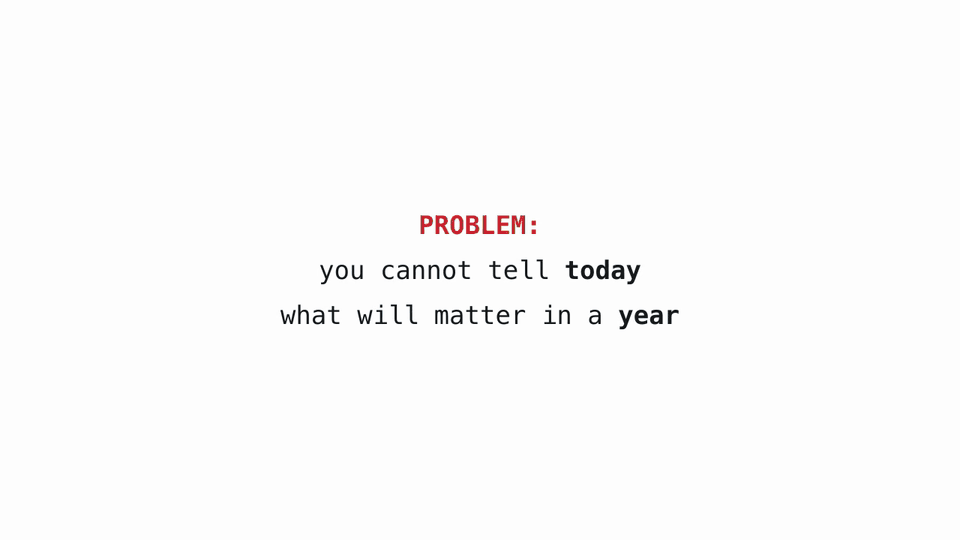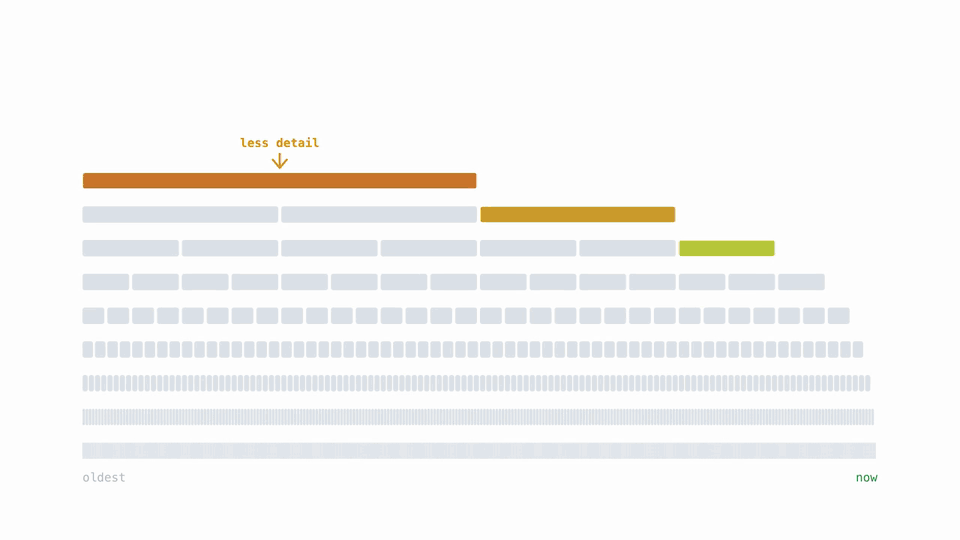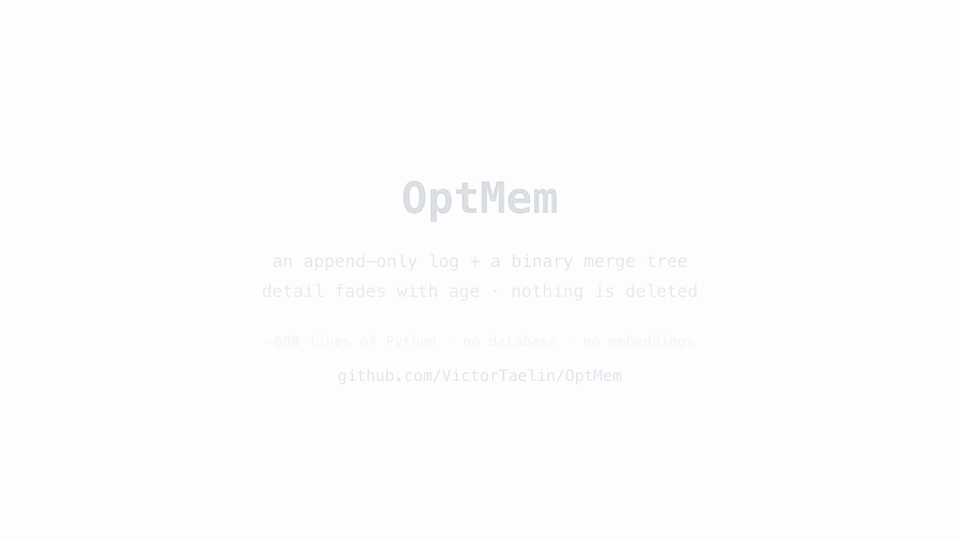
(same thing as a scrubbable video: optmem.mp4)
Setup
git clone https://github.com/VictorTaelin/OptMem ~/OptMem
~/OptMem/memo init
init creates ~/memory — this machine's identity — and prints a ## Memory
block with your paths filled in. Paste it at the top of your agent's
AGENTS.md (or CLAUDE.md). That is the whole integration: no daemon, no
database, no embeddings, no harness plugin. Claude Code, Codex, pi and a human
at a shell all use it the same way.
the block it prints, to read before you paste it
## Memory

Your memory is OptMem: the tool is `~/OptMem/memo`, the data is `~/memory`.
It survives every new session, every compaction and every change of
model or vendor. Without it you do not know who you are, or what was
already decided and tried.

Run `~/OptMem/memo wake` before any other tool call, in every session. It prints
in numbered parts, each ordering the next; run every one until a part
says `You are awake.` Do not stop early: part 1 is your distant past,
the last part is this week. If wake refuses because compressions are
pending, do them and run `~/OptMem/memo wake` again.

While you work:

- `~/OptMem/memo note "<one line, max 280 chars>"` the moment something happens,
  you learn something, or something changes -- if and only if it is new
  to you, important, and lasting in effect. That covers a task worth
  real effort, a fact or insight your user teaches you, anything you
  learn about their life (even indirectly), and work of yours that
  lands. Never write what you already know: no redundant memories, ever.
- If `~/OptMem/memo note` returns a compression, do it before your next action.
- `~/OptMem/memo recall <regex>` when a memory is too vague.
- Before your context ends, run `~/OptMem/memo sleep` and answer each prompt
  until it prints `Nothing left to compress.`
- Never create, edit or delete anything under `~/memory`:
  only the tool writes there.

Parallel sessions on this machine are all you, and may all write
memories. A subagent is not: it must never run `memo`, because it cannot
judge what is already known and its notes would arrive duplicated and at
the wrong grain. Start every brief you send one with `You are a
subagent. Do not run memo.` If your own first message is a task brief
from another agent, you are that subagent: skip this section.
Commands
memo init |
create the memory, print the block above |
memo wake |
read the memory context — first command of every session |
memo note "..." |
record one memory: one line, ≤ 280 chars |
memo sleep |
do the pending merges |
memo recall <regex> |
search every memory ever recorded, verbatim |
memo forget <lo>-<hi> |
drop a bad summary; the next sleep rebuilds it |
Merges are handed to the agent as they come due, so there is nothing to schedule and nothing to run in the background:
$ memo note "shipped the login fix to prod"
Saved as #4213.

Compress memories #4212-4213 into one line of at most 280 characters.
Keep every name, number, date, decision and outcome.
Drop wording, not facts. Invent nothing.

  #4212 2026-07-25 found the login bug: token expiry was in ms
  #4213 2026-07-25 shipped the login fix to prod

Run: memo sleep 4212-4213 "<your line>"
To correct a memory, append the correction — both lines are true history and
the next merge settles them. LOG.txt is never edited.
Configure
~/memory/config, written by init with every knob commented out:
# WAKE_LINES=208     # the memory context: how many lines wake prints (~16k tokens)
# ENTRY_CHARS=280    # the longest a single memory may be, in bytes
# PART_CHARS=20000   # output paging: largest part, in bytes
# PART_LINES=500     # output paging: largest part, in lines
WAKE_LINES is the one that matters. It is a reading budget, not a storage
budget: change it at any time, in either direction, with nothing to recompute.
Data
~/memory/
  LOG.txt   every memory, one per line, append-only, never edited
  TREE/     the merge summaries — a cache, rebuildable from the log alone
  config
Records are fixed width, so position is identity and every lookup is one
seek: no index that could disagree with the data, and both files stay
grep-able plain text. At one million memories (607 MB), wake takes 0.03s.
Test
python3 test.py
Limitations
Recency is the only axis: an important old memory fades like any other, and
the defence is rehearsal — noting it again makes it recent. recall is regex
over plain text, not semantic search; the memory context is what tells you
what to search for. Summaries are written by the agent from other summaries,
so a bad one propagates upward until you forget it. And a wake costs ~16k
tokens by default, which is deliberate but not free. If you need a fact
database, use a wiki or a retrieval system — this is for who the agent is.